Caching in Python with functools.cache, lru_cache and cached_property
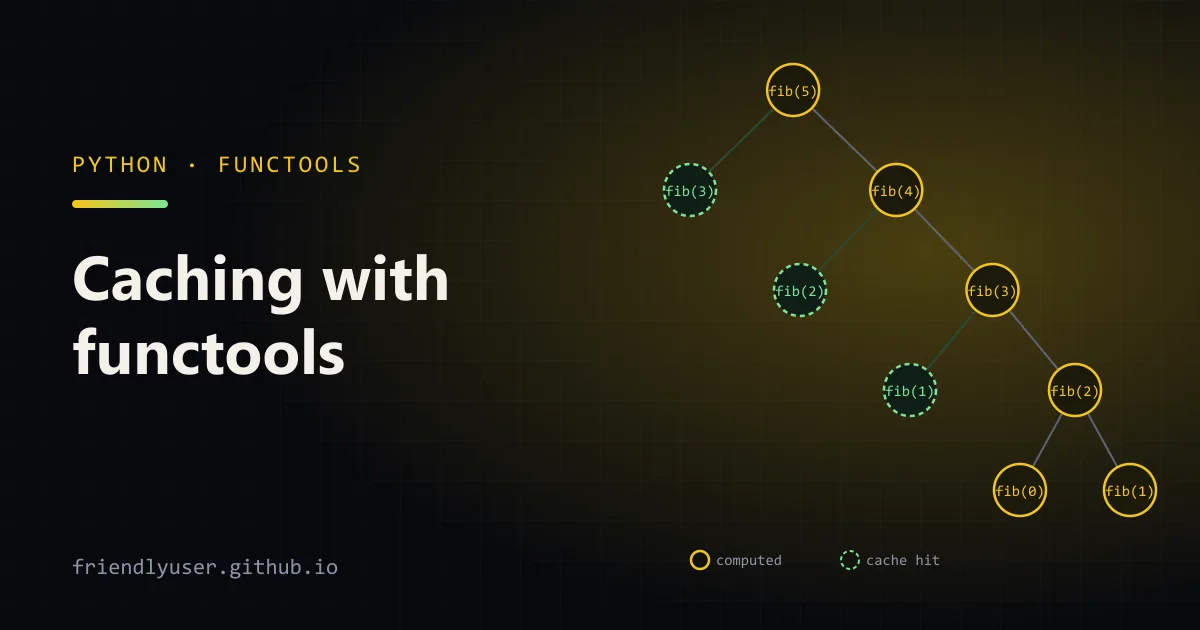
functools ships three caching decorators. cache and lru_cache memoise a function: they remember the result for each set of arguments and return it instead of calling the function again. cached_property computes an attribute once per instance and stores it on that instance. All three are in the standard library, need no setup, and are the right first step when the same expensive call happens many times with the same inputs.
They also have sharp edges: arguments must be hashable, results are never refreshed, and putting lru_cache on a method keeps every instance alive. This post covers how each one works, those pitfalls, and what to reach for when you need entries to expire. Examples were run on Python 3.12, with cachetools 7.1 for the TTL section.
cache: unbounded memoisation
Section titled “cache: unbounded memoisation”The textbook example is a recursive Fibonacci, which recomputes the same values exponentially many times:
import timefrom functools import cache

def slow_fib(n: int) -> int:    return n if n < 2 else slow_fib(n - 1) + slow_fib(n - 2)

@cachedef fib(n: int) -> int:    return n if n < 2 else fib(n - 1) + fib(n - 2)

t = time.perf_counter(); slow_fib(30); print(f"uncached fib(30): {time.perf_counter() - t:.2f}s")t = time.perf_counter(); fib(30); print(f"cached fib(30):   {time.perf_counter() - t:.6f}s")print(fib.cache_info())
uncached fib(30): 0.11scached fib(30): 0.000023sCacheInfo(hits=28, misses=31, maxsize=None, currsize=31)(Timings are from a single run and only show the size of the difference.)
@cache (Python 3.9+) is shorthand for @lru_cache(maxsize=None). The cache is a dict keyed by the arguments, and it never evicts anything. That is fine for a function with a small, fixed set of possible inputs: parsing a handful of config files, compiling a few regexes, looking up a country by code. It is a memory leak for a function called with unbounded input, such as user IDs or URLs.
lru_cache: a bounded cache
Section titled “lru_cache: a bounded cache”lru_cache(maxsize=N) keeps at most N results and evicts the least recently used one when it is full. The default maxsize is 128.
from functools import lru_cache

@lru_cache(maxsize=2)def square(x: int) -> int:    print(f"  computing {x}")    return x * x

for x in [1, 2, 1, 3, 2, 1]:    square(x)print(square.cache_info())square.cache_clear()print(square.cache_info())
computing 1 computing 2 computing 3 computing 2 computing 1CacheInfo(hits=1, misses=5, maxsize=2, currsize=2)CacheInfo(hits=0, misses=0, maxsize=2, currsize=0)Walk through it: 1 and 2 are computed; 1 is a hit and becomes the most recent; 3 is computed and evicts 2 (the least recently used); then 2 is a miss again and evicts 1, and 1 is a miss in turn. With only two slots, this access pattern thrashes. cache_info() is how you notice: a low hit count relative to misses means the cache is too small or the inputs do not repeat.
The two management functions every cached function gets:
cache_info()returns hits, misses,maxsizeand current size.cache_clear()empties the cache. Call it in test setup, or when the underlying data changes.
The original function is still available as square.__wrapped__ if you need to bypass the cache.
Arguments must be hashable
Section titled “Arguments must be hashable”The cache key is built from the arguments, so they must be hashable:
fib([1, 2])# TypeError: unhashable type: 'list'Lists, dicts and sets fail. Convert to a tuple or frozenset before calling, or have a small uncached wrapper do the conversion:
@lru_cache(maxsize=1024)def _score(words: tuple[str, ...]) -> int:    return sum(len(w) for w in words)

def score(words: list[str]) -> int:    return _score(tuple(words))
Hashable is not quite enough, either. The key is built from the arguments as passed, so calls that mean the same thing can end up as separate entries:
@lru_cachedef f(a, b=0):    print(f"  computing f({a}, {b})")    return a + b

f(1); f(1, 0); f(a=1)
computing f(1, 0) computing f(1, 0) computing f(1, 0)Three calls, three misses. Positional, explicit default and keyword forms are all different keys. That costs some hits but is never wrong. typed=True goes the other way and keeps f(1) and f(1.0) apart, which you want when the type changes the result.
The other requirement is that the function is deterministic and has no side effects you rely on. A cached function that reads the clock, a file or a database returns the first answer forever.
The method-caching memory leak
Section titled “The method-caching memory leak”This looks reasonable and is a classic leak:
import gcimport weakreffrom functools import lru_cache

class Report:    def __init__(self, rows: list[int]) -> None:        self.rows = rows
    @lru_cache(maxsize=None)    def total(self) -> int:        return sum(self.rows)

r = Report(list(range(1_000_000)))alive = weakref.ref(r)r.total()del rgc.collect()print("Report still alive after del:", alive() is not None)Report.total.cache_clear()gc.collect()print("after cache_clear:", alive() is not None)
Report still alive after del: Trueafter cache_clear: FalseThe decorator wraps the function on the class, so there is one cache shared by every instance, and self is part of each key. The cache holds a strong reference to every Report that ever called total(), along with its million-item list. With maxsize=None they are never released. With a bounded maxsize they are released eventually, but one instance’s entries can also evict another’s.
Ruff and flake8-bugbear flag this pattern as B019. There are three fixes, depending on what you need.
Fix 1: cached_property for zero-argument methods
Section titled “Fix 1: cached_property for zero-argument methods”If the method takes no arguments besides self, it is really a computed attribute:
from functools import cached_property

class Report:    def __init__(self, rows: list[int]) -> None:        self.rows = rows
    @cached_property    def total(self) -> int:        print("  summing")        return sum(self.rows)

r = Report([1, 2, 3])print(r.total, r.total, r.__dict__) summing6 6 {'rows': [1, 2, 3], 'total': 6}cached_property runs the method on first access and stores the result in the instance’s __dict__ under the same name. Later lookups find the instance attribute and never call the method again. The cached value lives and dies with the instance, so there is no leak.
It does not notice when the data it was computed from changes:
r.rows.append(4)print(r.total) # still 6del r.total # drop the cached valueprint(r.total) # summing, then 10Two more limits: it needs an instance __dict__, so it fails on classes with __slots__ (TypeError: No '__dict__' attribute on 'Slotted' instance to cache 'total' property.), and since Python 3.12 it no longer takes a lock, so two threads can both compute the value the first time. If that matters, add your own lock.
Fix 2: a cache per instance
Section titled “Fix 2: a cache per instance”If the method takes arguments, build the cache in __init__ so each instance owns its own:
from functools import lru_cache

class Client:    def __init__(self) -> None:        self.lookup = lru_cache(maxsize=256)(self._lookup)
    def _lookup(self, key: str) -> str:        return key.upper()
The instance and its cache reference each other, which is a cycle, but the garbage collector reclaims it once nothing else refers to the instance.
Fix 3: cache a plain function
Section titled “Fix 3: cache a plain function”Often the cached work does not need self at all. Move it to a module-level function that takes only the values it uses, and cache that. This is usually the cleanest option.
Expiring entries: a TTL needs a library
Section titled “Expiring entries: a TTL needs a library”functools has no time-based expiry. For data that goes stale, such as exchange rates, feature flags or tokens, use cachetools, which provides TTLCache and a cached decorator that works like lru_cache:
import time
from cachetools import TTLCache, cached
calls = 0

@cached(cache=TTLCache(maxsize=1024, ttl=0.5))def exchange_rate(base: str, quote: str) -> float:    global calls    calls += 1    return 1.37  # pretend this came from an HTTP API

exchange_rate("USD", "CAD")exchange_rate("USD", "CAD")print("calls after two lookups:", calls)time.sleep(0.6)exchange_rate("USD", "CAD")print("calls after the TTL expired:", calls)
calls after two lookups: 1calls after the TTL expired: 2Run it with uv run --with cachetools ttl.py. TTLCache is also bounded by maxsize, evicting least recently used entries when full. Unlike lru_cache, the cachetools decorators are not thread-safe by default; pass lock=threading.Lock() to cached if several threads share the cache.
For a cache shared between processes or servers, an in-memory dict is the wrong tool altogether. That is a job for Redis or memcached.
Gotchas
Section titled “Gotchas”- Don’t put
@cacheon anasync def. It caches the coroutine object, and a coroutine can only be awaited once. The second call fails withRuntimeError: cannot reuse already awaited coroutine. Cache the awaited result yourself, or use a library built for async caching. - Mutable return values are shared. If a cached function returns a list and a caller appends to it, every later caller sees the change. Return tuples or frozen objects, or copy at the call site.
- Exceptions are not cached. If the function raises, nothing is stored and the next call tries again. That is usually what you want for transient errors.
- Tests leak state through caches. A cached function keeps results across tests. Call
cache_clear()in a fixture, or test the__wrapped__function directly. - Check that caching helps.
cache_info()on a real workload tells you the hit rate. A cache with mostly misses only adds memory and hashing cost.
Further reading
Section titled “Further reading”© 2026 David Li · Home · Blog · RSS ·Classic site · Built with Astro, Starlight and three.js · Logos:Font Awesome Free (CC BY 4.0)